The August 26 AWS-Nvidia announcement plans two million additional GPUs for 2027-2028. It extends the earlier plan for more than one million starting in 2026. These are deployment commitments, not a count of GPUs available to customers today.
Read “additional” and “planned” together
The joint announcement names Blackwell Ultra, Rubin and Rubin Ultra in the future expansion. It also describes work on CPUs, networking and software. Those programs have distinct deliverables; one headline does not establish a common launch date for all of them.
The earlier baseline is more than one million, not exactly one million. Adding two million to that statement does not establish an exact tripling of a measured installed fleet.
A GPU count is not an application benchmark
Equipment from different generations is not a single interchangeable unit of useful work. Memory capacity, bandwidth, interconnect, precision and the software path can change which workloads fit and how they scale. The global fleet also includes capacity in different regions and availability domains.
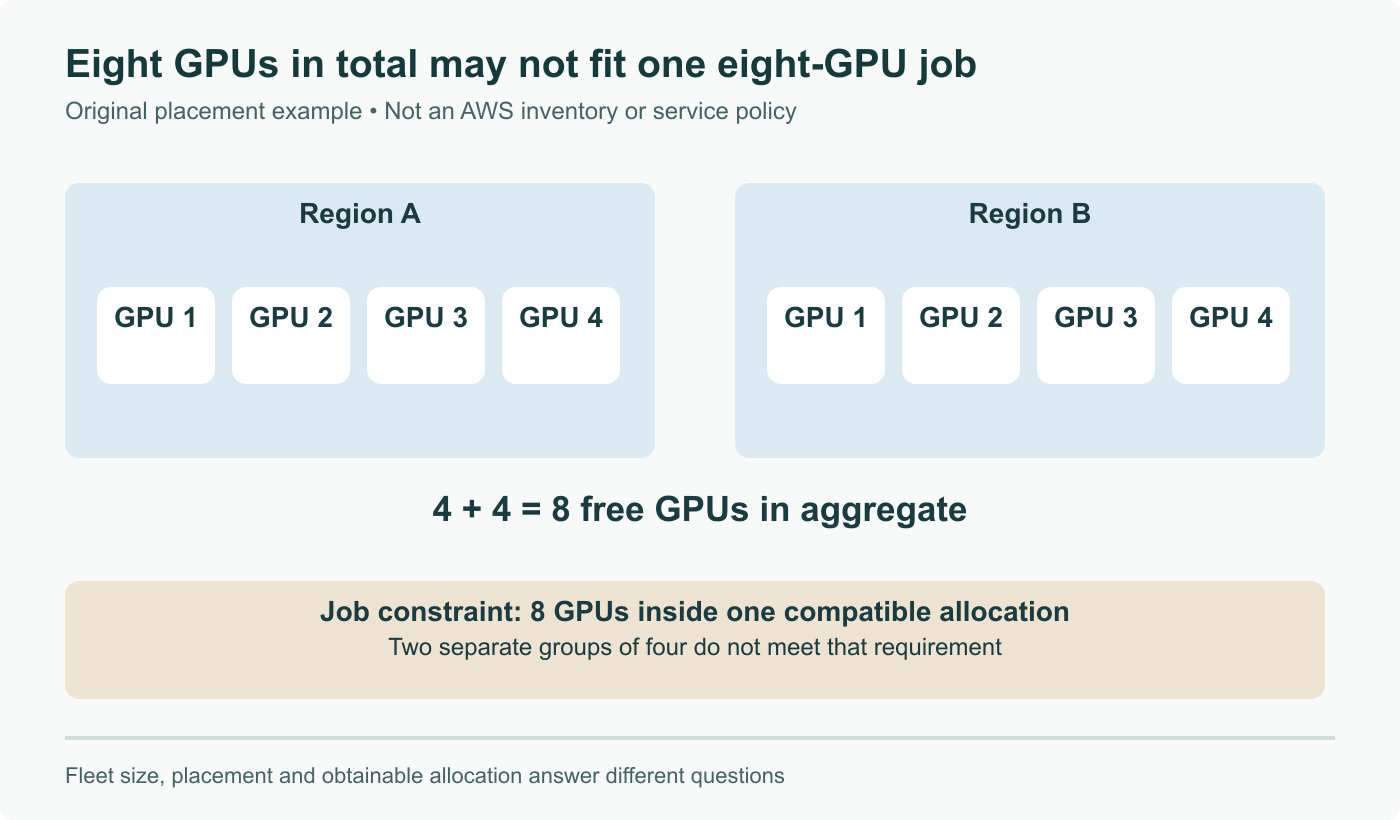
An original scheduling example makes the placement issue concrete. Imagine a job requiring eight GPUs connected within one supported allocation. A provider with four spare GPUs in one region and four in another has eight spare GPUs in total, but that does not satisfy this job's requirement. The example is not a description of AWS's allocation policy; it shows why an aggregate inventory is insufficient evidence of availability.
What a customer can actually compare
For a deployment decision, record the instance type, region, quota and reservation arrangement that can be obtained. Then check usable accelerator memory and interconnect for the intended model and batch size. Pricing and regional availability must be checked for that offering when it becomes available.
For inference, a useful comparison holds model, precision, input length, output length and latency target constant. Report completed requests that meet that target alongside cost. A configuration producing more tokens while missing every response deadline may be unsuitable for the application.
For training, time to a specified result is more useful than adding theoretical arithmetic peaks. Checkpointing, data delivery and communication can dominate at scale. No such application result follows from this equipment roadmap, and PeopleAreGeek has not benchmarked the announced future fleet.
Keep 2027-2028 capacity as a plan; remove exact tripling and implied performance conversion.