The IBM and Together AI announcement is a commercial infrastructure agreement. Its headline value is not a purchase price per GPU, and the announced cluster is not yet a delivered service.
The announced arrangement
The August 11 IBM release describes a $240 million multi-year agreement. IBM plans an HGX B300 cluster with NVIDIA Spectrum-X networking on IBM Cloud, expected in the first quarter of 2027, to support Together AI inference. The release does not describe an equity investment in Together AI.
The roles matter: IBM provides the cloud infrastructure; Together AI brings the inference service and its users. The planned availability date belongs alongside the hardware names. It prevents a reader from interpreting an expansion commitment as capacity already serving requests.
Why the headline cannot give a GPU price
Dividing a contract value by an assumed GPU count would mix unlike quantities. A multi-year service can include hardware access, networking, operations and support over time. The announcement does not give the complete cost breakdown needed to isolate an acquisition price.
Even with a reliable hardware count, you would still need the term and included services. A GPU, a server containing several GPUs and a whole cluster are also different units; the release does not justify filling those missing denominators with guesses.
Capacity is useful only through completed work
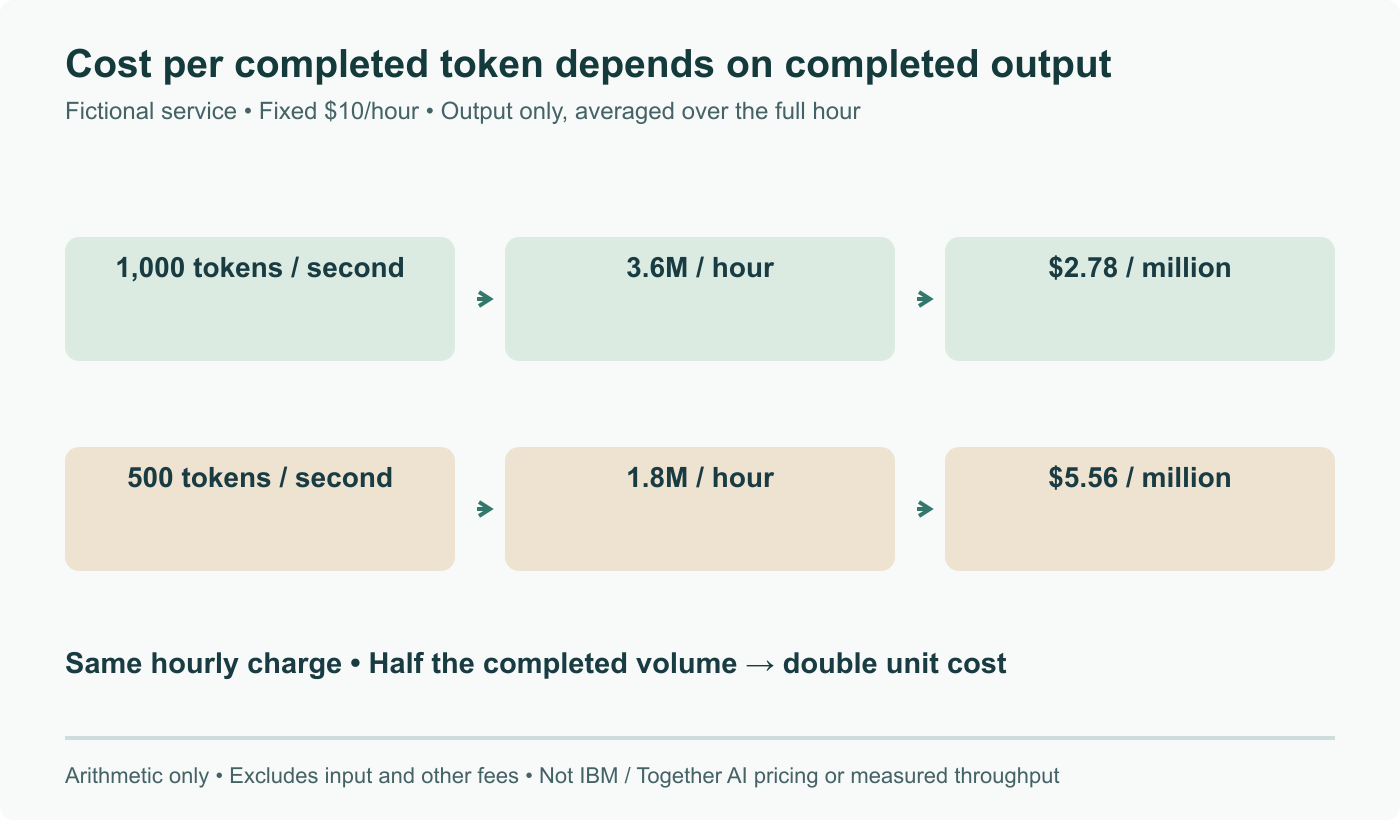
Our separate fictional example assumes a service costs $10 per hour and completes an average of 1,000 output tokens per second over that hour. It delivers 3.6 million tokens, making the service component about $2.78 per million output tokens. At 500 completed tokens per second for the same hourly charge, that component becomes about $5.56.
These are arithmetic examples, not IBM or Together AI prices or throughput. Input processing, other charges and latency constraints are excluded. The cover keeps the cost and completed-output denominator visible.
For an actual inference service, compare the same model and workload with a stated latency target, error rate and concurrency. A hardware specification helps describe the deployment; it cannot alone establish the cost or reliability of a completed user request.
Correct commercial agreement versus equity investment; preserve planned Q1 2027 delivery; remove unsupported system count and implied unit pricing.