A lower model bill does not necessarily mean a cheaper completed task. The useful denominator is a result that meets the same acceptance criteria.
What the foundation announced
The Linux Foundation’s August 4 launch describes planned AI cost and value frameworks, including token telemetry for FOCUS 1.5 and beyond. This is a roadmap, not proof that those fields are already emitted by every provider. The FOCUS site currently presents version 1.4 and shows providers exporting different specification versions.
Normalizing billing records can help compare charges. It does not automatically decide whether an answer, classification or completed workflow was useful. That requires an application-level definition of success.
Worked example: the cheaper request loses
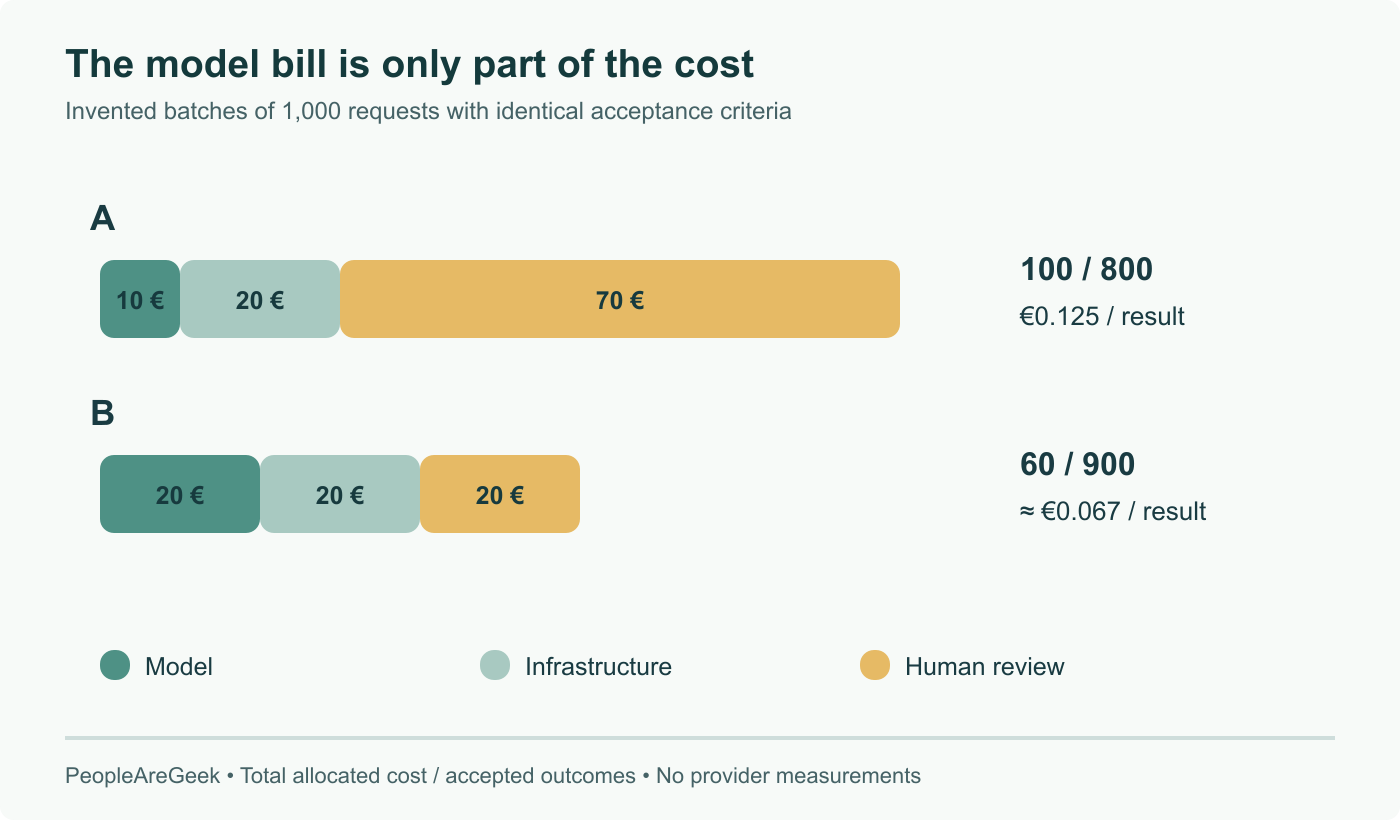
Assume two systems process the same 1,000 requests. All figures below are fictional and use the same acceptance test. We allocate model, supporting infrastructure and review costs to that batch.
| Batch | Model | Infrastructure | Review | Total | Accepted results | Cost per accepted result |
|---|---|---|---|---|---|---|
| A | €10 | €20 | €70 | €100 | 800 | €0.125 |
| B | €20 | €20 | €20 | €60 | 900 | about €0.067 |
A has the cheaper model line, but its total cost per accepted result is higher: 100 / 800, compared with 60 / 900. This is not a provider benchmark or an ROI calculation; revenue, benefits and avoided costs are absent.
Make the denominator auditable
Define acceptance before comparing models. Keep failures and retries in the cost numerator instead of silently dropping their invoices. Count the final accepted task once, even if several model calls contributed to it. If human corrections are necessary, include that labour consistently rather than only for one candidate.
For each batch, preserve the model revision, pricing period, request category, supporting costs and acceptance method. A later price change should be distinguishable from improved task quality or a different mix of requests.
When adopting a billing schema, check the actual exported version and the fields your consumer reads. A tool’s ability to parse one FOCUS dataset does not prove that it can interpret every future AI-specific extension. The standard and the outcome metric solve related but different parts of the accounting problem.
September 8: distinguish the foundation roadmap from delivered schemas, check current FOCUS 1.4 and give an explicit cost-per-accepted-result example.