Taalas specializes silicon for a model. AMD’s agreement gives that approach a place in its plans, but a fast token-generation figure does not specify the latency or quality of an entire application.
The agreement and the hardware demonstration
AMD’s August 6 announcement confirms an acquisition agreement subject to closing conditions and regulatory approvals. Integration with Instinct is planned. The announcement does not establish that an integrated AMD product has shipped.
Taalas calls HC1 a technology demonstrator running Llama 3.1 8B, with vendor-reported generation around 17,000 tokens per second per user. Its technical explanation describes model-specific silicon, configurable context and LoRA support. It also acknowledges quality degradation from HC1’s mixed 3-bit and 6-bit parameters. That qualification matters when comparing speed with other implementations.
Calculate the part a user experiences
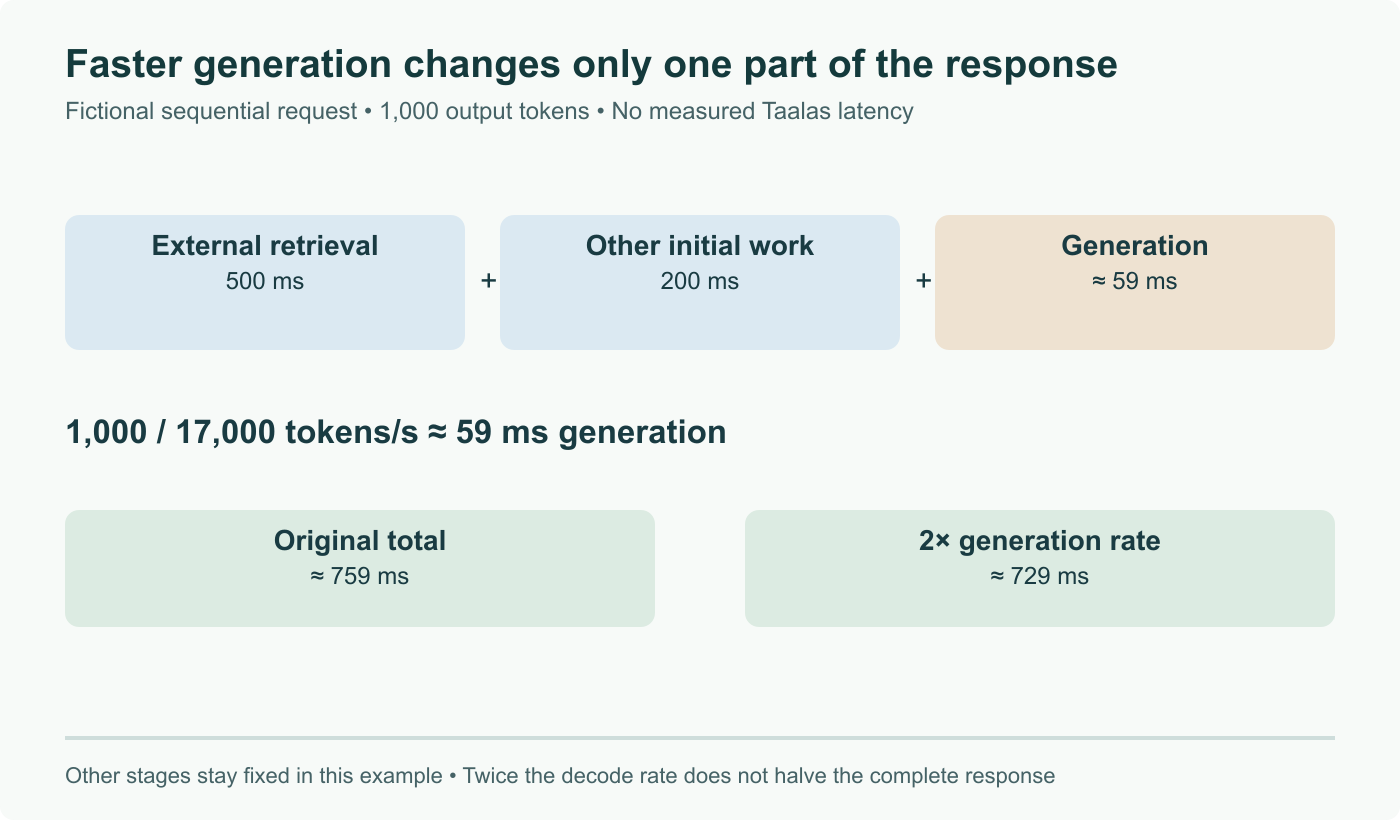
The cover uses a fictional request with 1,000 output tokens, generated at 17,000 tokens/s. The generation term is about 59 ms. Add a hypothetical 200 ms before generation and 500 ms retrieving external data: the response takes roughly 759 ms under this simplified sequential model.
Making generation twice as fast saves about 29 ms, not half the entire response time. Real services may overlap stages, stream partial results or incur extra tool calls; the example is not a measured HC1 request. It shows why a decode-rate headline cannot replace a latency breakdown.
Specialization changes the update question
A programmable accelerator loads different weight files. Hardware built around one model requires a different deployment discussion: which changes fit within supported adaptation, which need new silicon, and how long the chosen model remains useful. LoRA support does not make every model replacement a software update.
The old article also claimed that every token always reads every model weight. That is too broad: routed experts and batching change the work and memory traffic. Likewise, prefill and decode bottlenecks depend on workload and hardware rather than obeying one absolute rule.
For a real comparison, hold the task and quality threshold fixed. Record time to first token, generation rate, concurrent users and complete response time. A specialized system may be compelling for a stable, high-volume task; the evidence should show that task, not just its fastest internal stage.
September 8: distinguish acquisition agreement from closing, label HC1 vendor performance and quantization limits, and replace absolute inference claims with an end-to-end latency example.