AMD’s August 27 ROCm 10 announcement brings together a new release foundation and ROCm.AI developer tools. The CLI and AMD Skills have preview status. A shared release name does not mean every component has identical maturity or platform coverage.
Read the status of each component
AMD's release overview identifies TheRock as the build foundation and describes an approximately six-week release cadence. It labels the ROCm CLI a tech preview and places repository consolidation in future releases. The AMD Skills overview also labels the catalog a tech preview.
For adoption, check the component, GPU and operating system you actually intend to use. A common SDK release does not establish that every library, framework or optimization tool supports every advertised hardware family.
What Hyperloom tries to optimize
The Hyperloom documentation describes an iterative system for profiling inference, identifying bottlenecks, changing host or GPU code and validating the result. Its output includes proposed code changes and a report. The documentation's Linux scope should not be silently extended to all ROCm platforms.
An optimizer finding a faster kernel is a useful intermediate result. The application-level gain depends on how much of the original runtime that kernel occupied and whether the revised computation still meets the required accuracy.
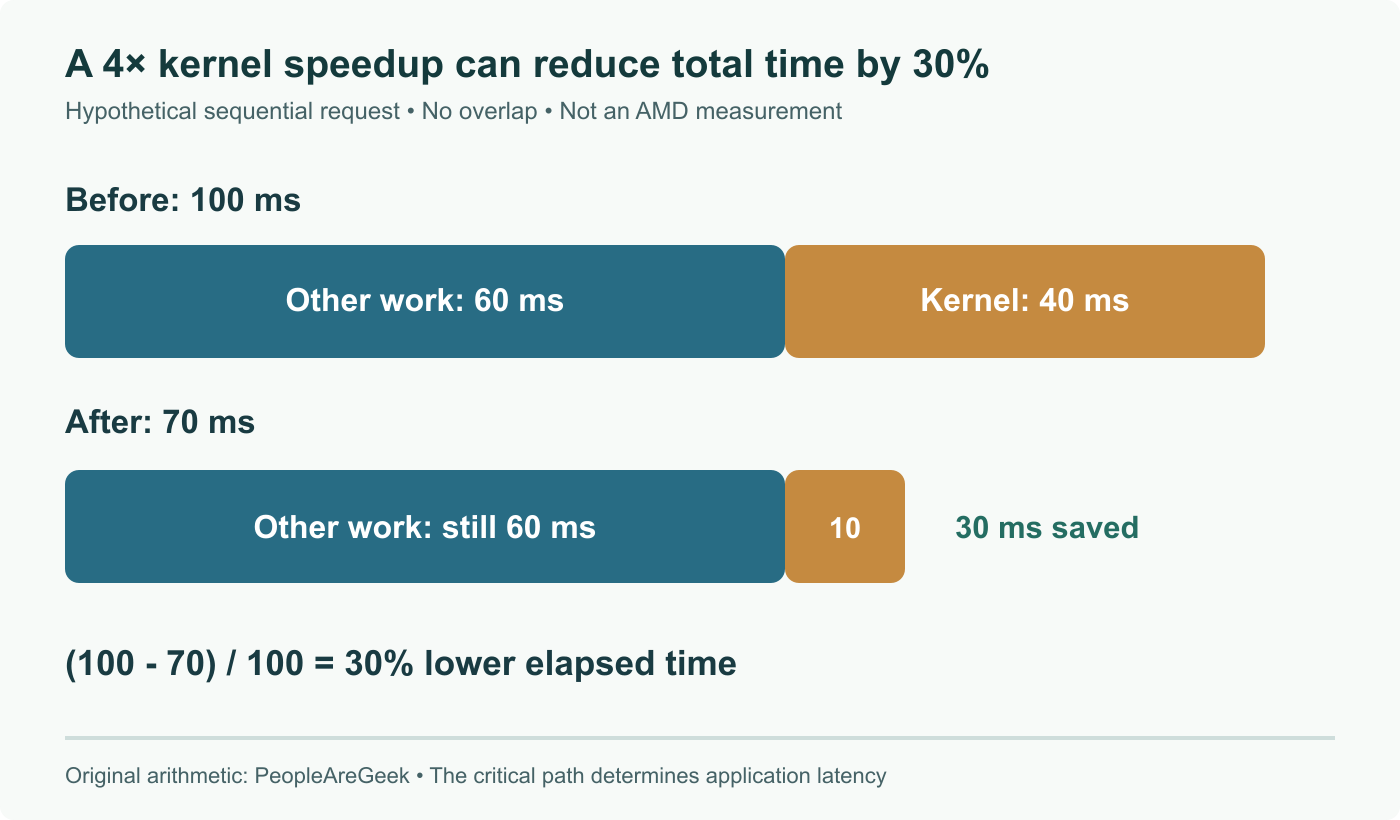
A four-times faster kernel can save 30% overall
Consider a hypothetical sequential request taking 100 ms: 60 ms outside the targeted GPU kernel and 40 ms inside it. If that kernel becomes four times faster, its contribution falls to 10 ms. The request then takes 70 ms, not 25 ms.
The elapsed-time reduction is 30%. Under the additional assumption of one request at a time with no other limiting factor, throughput would rise by 100/70, approximately 1.43 times. These numbers are an original teaching example, not an AMD benchmark.
Parallel execution, overlapping transfers and batching require a more detailed model. In particular, adding per-kernel timings can overcount time when work overlaps. Use the complete request timeline to identify the actual critical path.
A useful record of an optimization attempt
Keep the original code, input shapes, precision, software versions and hardware configuration together. Define correctness tolerances before searching for faster implementations. Then compare repeated end-to-end measurements under the same warm-up and concurrency conditions.
Record failed candidates as well as the chosen one: a kernel that becomes faster by producing the wrong values is not an optimization. Also test input sizes outside the single case used during tuning if the application must support them.
ROCm.AI can help organize that work. The release announcement alone supplies neither the compatibility result for your machine nor the performance result for your model.
Distinguish ROCm 10 release from tech-preview tools and planned repository changes; add a transparent end-to-end optimization calculation.