IBM released Granite 4.2 on August 25 in 3B, 8B and 30B sizes under Apache 2.0. All support thinking controls and tool calling. The smallest model does not share every reinforcement-learning stage of the larger two.
The size difference is also a training difference
IBM's technical account reserves its agentic reinforcement-learning block for 8B and 30B. Tool-call support in 3B therefore should not be described as proof of identical agent training or task performance.
The 3B model card documents thinking, non-thinking and low-effort modes. It distinguishes native 128K context from extension to 512K. The effective serving limit still depends on the selected configuration and available memory.
Weight size is not the whole memory requirement
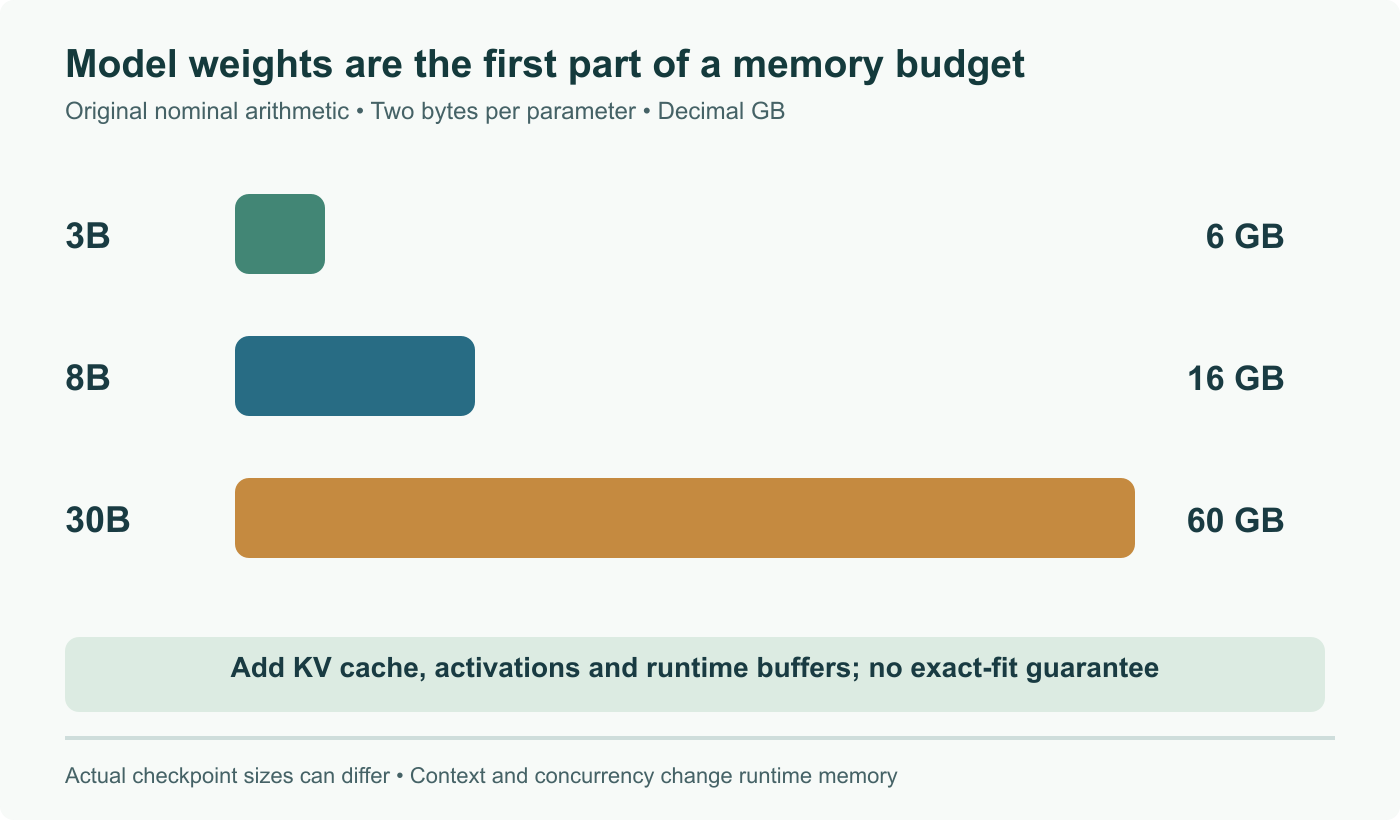
An original lower-bound estimate starts with nominal parameter count. At two bytes per parameter, three billion parameters require about 6 GB in decimal units for weights alone; eight billion need about 16 GB and thirty billion about 60 GB. Real checkpoint sizes and implementation details can differ.
Those figures exclude the KV cache, temporary activations, runtime buffers and other allocations. They are not a promise that a model will run on a device with exactly that memory capacity. Quantized weights change the calculation and introduce their own representation details.
For example, if a hypothetical deployment already uses 6 GB for weights, adding a 2 GB cache budget means at least 8 GB before the remaining runtime allocations. Increasing context or concurrent requests can change the cache requirement even when the model file is unchanged.
Compare modes on outcomes, not reasoning length
A practical evaluation can use a fixed set of your own tasks with answers that can be checked. Run each mode with the same prompt formatting, output budget and serving configuration. Count correct final results and measure time to the final answer.
For a tool task, also validate the tool name and arguments and whether the requested operation is authorized. A syntactically valid function call is not proof that it is the right action. A long reasoning trace is not a substitute for either check.
PeopleAreGeek has not benchmarked these checkpoints. The release is useful because it offers several sizes and deliberation settings to evaluate; selecting one should follow the application budget and measured success rate, not the assumption that more thinking always improves the result.
Distinguish shared thinking/tool support from 8B/30B-only agentic RL; explain context and memory with explicit arithmetic.