OpenAI published Jalapeño inference results on August 25. They compare latency and throughput per kilowatt across public models. The key qualification is the denominator: the published comparison uses accelerator power ratings, not a measurement of complete data-center consumption.
What was compared
The official results cover GPT-OSS 120B, DeepSeek R1 and Kimi K2.5 against specified GB200 or GB300 configurations. OpenAI normalizes using rated chip power, including 700 W for Jalapeño. The reported 1.5-1.9 times peak-throughput advantage should retain that basis and vendor attribution.
The initial platform announcement and August update describe deployment planned by the end of 2026. Measured hardware in a test and a broadly deployed production service are different states.
Rated-power normalization is not a wall-meter result
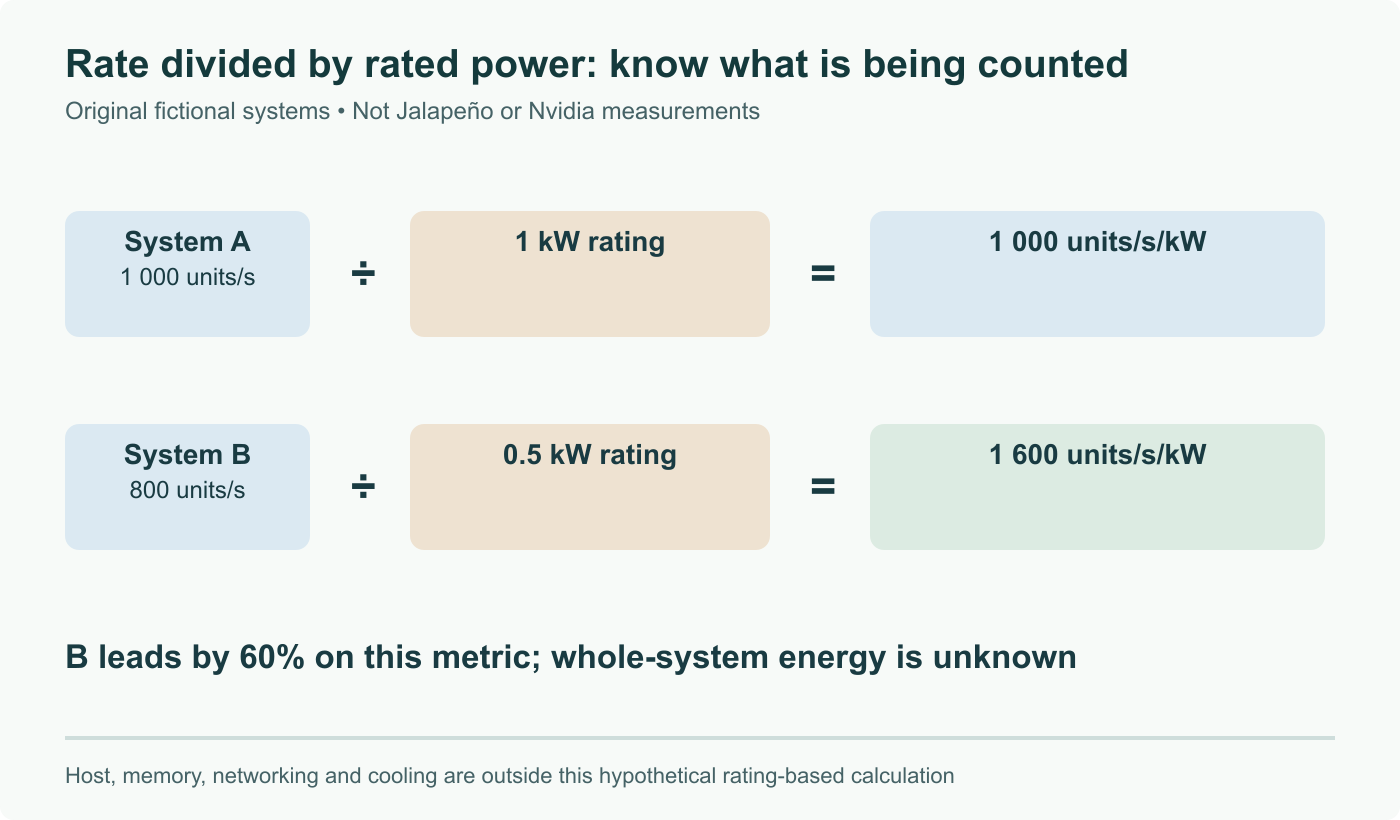
Consider an original example with two fictional systems. A completes 1,000 units of useful work per second with a 1 kW accelerator rating; B completes 800 with a 0.5 kW rating. Their normalized rates are 1,000 and 1,600 units/s/kW respectively. B leads by 60% on this metric.
That calculation does not tell us the electricity consumed by either entire system. It excludes unknown contributions from host processors, memory, networking and cooling, and it uses ratings rather than measured draw. Replacing one system's rating with measured power while leaving the other's rating would change the basis asymmetrically.
The example explains the denominator; its numbers are not Jalapeño or Nvidia results.
Keep the latency target with the throughput
A system's highest throughput may occur at a different concurrency and latency from its fastest individual response. Compare peak throughput with peak throughput, or compare both systems at a shared latency requirement. Do not take the best latency from one operating point and the best throughput from another and present them as simultaneous.
For an application assessment, retain model and precision, prompt and output lengths, concurrency, power boundary and the exact completion criterion. A claim about a selected kernel is also not a full-model claim; the August post explicitly distinguishes its block-level optimization results.
PeopleAreGeek has not reproduced these measurements. The disclosure provides configurations, operating points and a power-normalization method that readers can inspect. Those conditions are essential to interpreting the result.
Use official August results; distinguish rated accelerator power from measured facility energy and peak from matched latency.