Samsung’s Hot Chips presentation describes LPDDR5X-PIM, which places arithmetic beside DRAM banks. The advertised 614 GB/s concerns the internal PIM path. It should not be read as an ordinary 614 GB/s transfer link from the memory package to a processor.
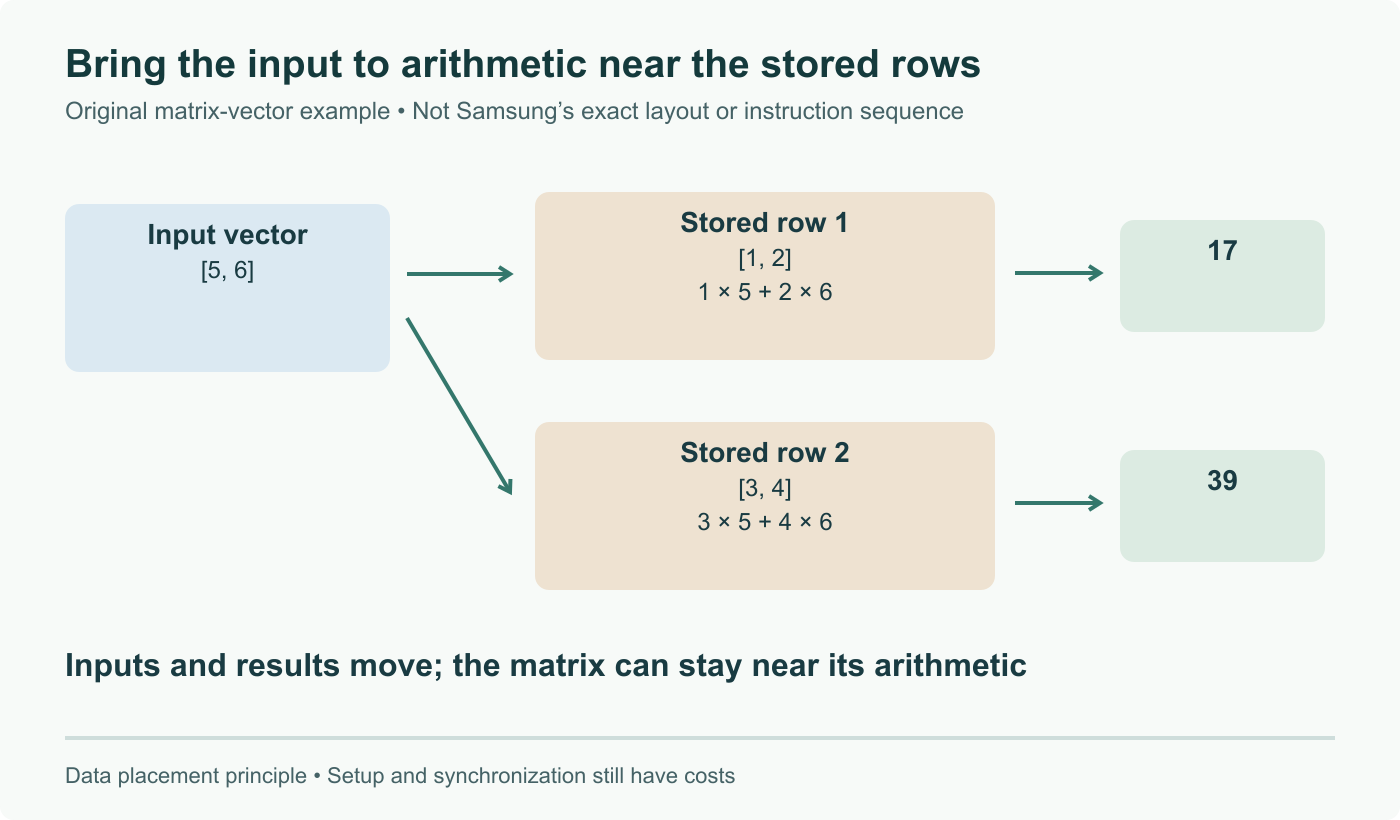
Follow where the arithmetic happens
Samsung's technical paper explains a PIM block associated with each bank and a software layer that places data and controls execution. Moving the arithmetic near the stored weights can avoid repeatedly carrying those weights over the external memory interface.
In a small original matrix-vector example, two stored rows, [1, 2] and [3, 4], multiply the input [5, 6]. The outputs are 17 and 39. A PIM-style organization can bring the input to arithmetic near the rows and return the smaller result, rather than moving the entire matrix to a remote arithmetic unit for that operation.
This example explains data placement, not Samsung's exact instruction sequence or supported precision. Inputs, outputs, setup and synchronization still need to move or execute; processing in memory does not eliminate all communication.
The presentation reports several different metrics
The Samsung slides reproduced by ServeTheHome distinguish 76.8 GB/s conventional DRAM bandwidth from roughly 614 GB/s PIM bandwidth at the stated configuration. Their silicon demonstration uses Llama 3.1 8B with integer formats and a short context, not an arbitrary model and workload.
The reported output rate rises from 27.0 to 81.3 tokens/s, about 3.01 times. The separately reported runtime changes from 12.3 to 5.4 seconds, about 2.28 times. Those ratios are not interchangeable, and neither establishes an eight-times application speedup from the bandwidth ratio.
Software and workload shape remain part of the result
The earlier paper is a simulation study. Its matrix-operation results must not be relabeled as the later silicon demonstration. It shows why mapping and synchronization matter: tiling can leave compute blocks idle, and ordering overhead can consume part of the gain.
For a useful application comparison, keep the same task, numerical requirements and output-length policy, then measure the whole execution. Also identify the work left on the host. Compatibility with a memory controller does not mean an unchanged application automatically emits PIM operations.
PeopleAreGeek has not tested this memory. The explanatory diagram is original; the performance figures remain Samsung's reported demonstration, with the public slide source supplied so their conditions can be inspected.
Separate internal PIM bandwidth, model output rate and full runtime; attribute silicon slides and distinguish earlier simulator paper.